
Why AI Characters Change Between Scenes and How to Fix It
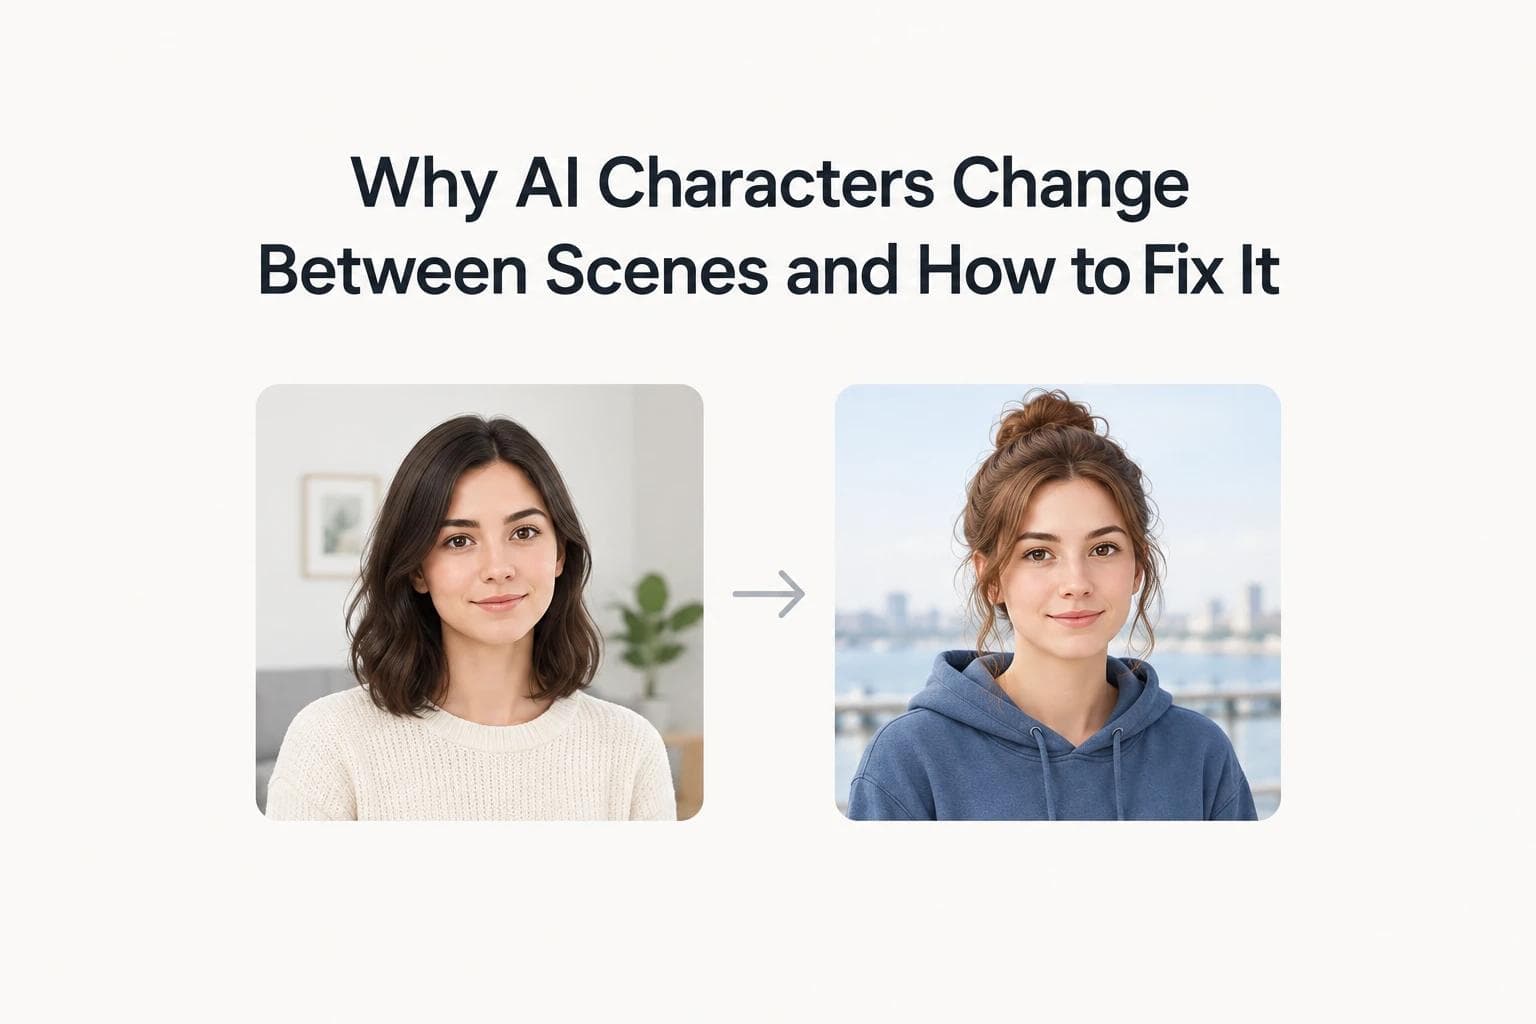
Scene one lands perfectly. The face is right, the jacket is right, you finally have the character you pictured.
Then scene three hands you a stranger with the same haircut.
Here is what is actually happening, cause by cause, and what to do about each one. Including the one nobody writes about: fixing a single broken shot without regenerating the whole video.
The short answer
Your model has no memory. Every generation starts from fresh noise and rebuilds your character from whatever the prompt and reference happen to say.
So far, so familiar. Most guides stop there.
The useful half is what the model does with the parts you left out. It does not leave them blank. It guesses, and it guesses differently every time.
One creator tested this properly. They designed an anime character with navy hair and warm hazel eyes, then generated a clip from a reference image taken from behind.
The eyes were never visible in that reference.
The clip came back with blue eyes. Blue hair, blue eyes, a perfectly reasonable guess. The headphones arrived with black ear pads too, invented, because the reference only ever showed the outside of the cups.
What the reference shows, the model keeps. What the reference hides, the model invents.
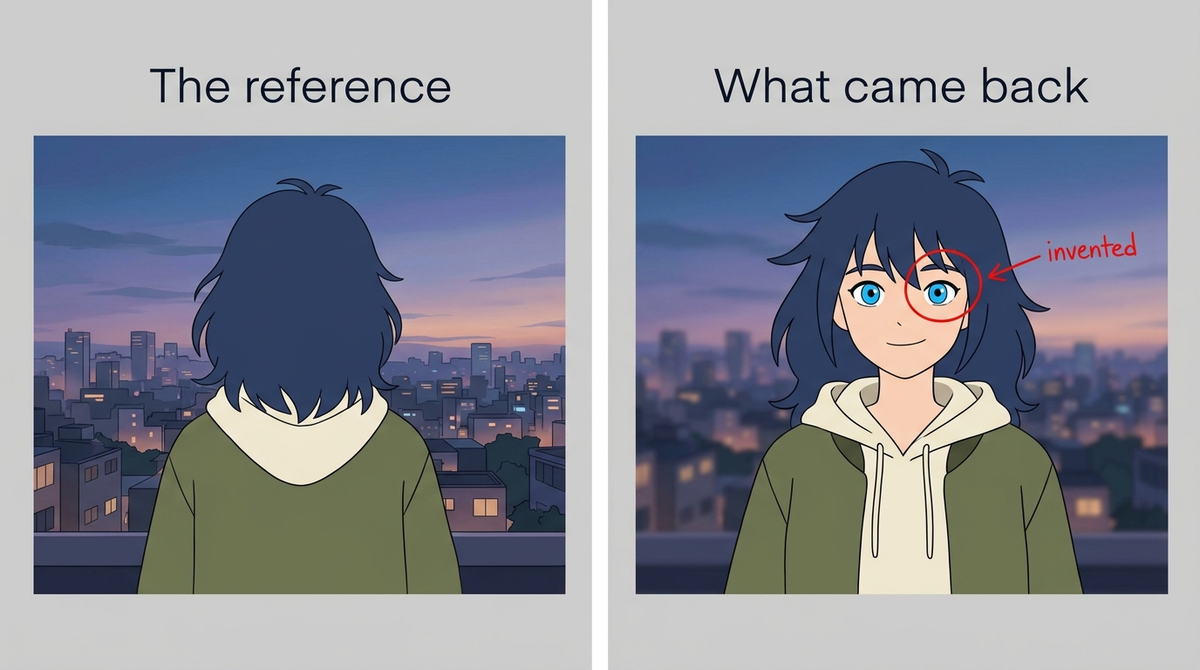
The reference never showed her eyes. So the model picked some.
That one sentence explains almost everything below.
Why do my AI-generated videos look inconsistent?
Because you are asking a stateless system to do a continuity job, and the gaps are where it improvises.
Four things widen those gaps:
- Vague descriptions. "A young woman in a jacket" leaves the model hundreds of decisions to make. Face shape, hair length, jacket cut, proportions. It resolves them fresh each time.
- Shifting wording. "Young anime girl" in scene one and "cinematic heroine" in scene two are two different targets.
- Incomplete references. Covered above. A back view cannot tell the model about eyes.
- Busy scenes. Ask for a crowded market and the model spends its attention on the market.
That last one surprises people. Google's own guidance now flags it: in a complex scene, the model dedicates its limited focus to the environment and the character's details drift. The more you ask for in a shot, the less of its attention your character gets.
At scale this compounds into something worse than an aesthetic problem. Produce twenty videos and you are not managing one character, you are managing twenty independent interpretations of one description.
Why the reference image is usually the problem
So you tighten the prompt. More adjectives, more detail, a longer description of the face.
Does it help? A little. But you are fixing the wrong file.
Most drift traces back to the reference, not the prompt.
Build the sheet properly and most of this disappears:
- Front, three-quarter, side, back, and a close-up
- The wardrobe visible, including the parts that matter
- A plain background, even lighting
- Nothing in the character's hands
Three to five images, not ten. Kling, Luma and Hailuo all cap reference inputs at four, which tells you something. Pile in more and they average together into something softer than any single one.
Whichever number you land on, you are re-attaching those files at the start of every session, for every video, forever. That is the part nobody mentions.
One clean front-facing portrait beats six moody atmospheric shots. Every time.
Why does prop design affect character consistency?
Because the model does not know where your character ends and the prop begins.
Hand your character a coffee cup in the master reference. Harmless, right?
Some generations fuse it to their fingers. Some change the cup's colour. Some drop it and leave the hand in a strange claw shape, because the hand was drawn around an object that is no longer there.
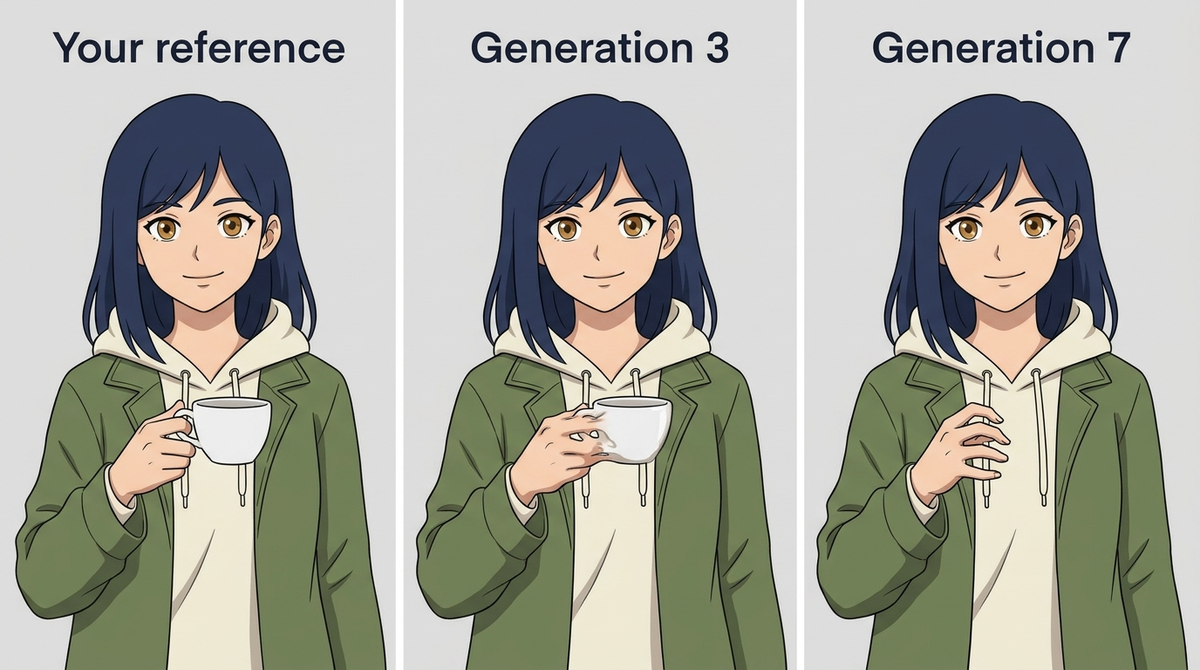
Put a cup in the reference and the model stops knowing where the hand ends.
The fix is boring and it works. Generate the character sheet empty-handed, then add props per shot in the prompt.
Same rule for anything removable. Bags, weapons, instruments, hats. If it can leave the character's body in the story, it should leave their body in the reference.
Wardrobe is the sharper version of this problem. Clothing drifts before faces do, and almost nobody checks for it. A reader who would notice a different nose will not consciously notice the jacket turning from olive to teal. They will just feel that something is off.
So be specific where it counts. "A dark navy wool coat with silver buttons" survives between scenes. "A coat" does not.
Why aren't negative prompts enough to enforce a consistent style?
Negative prompts remove things. They do not specify anything.
Write no photorealism, no 3D render, no harsh shadows and you have told the model three things it must avoid out of a near-infinite set of options. What fills the space it just cleared? Whatever the model would have done anyway, minus those three.
This is why stylised work drifts faster than realistic work. Models have a default pull toward photorealism, and a negative prompt is a fence rather than a destination.
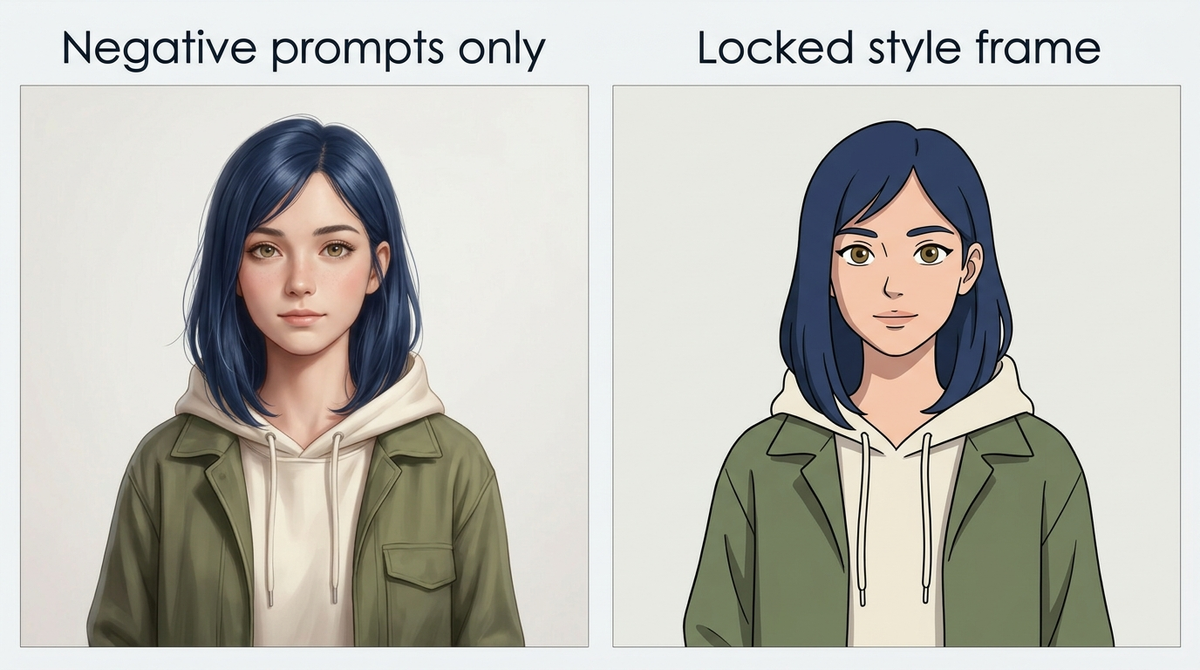
Same character, same wardrobe. Only one of these was given a style to aim at.
What actually holds a style:
- A style frame. One image that fixes palette, line quality and lighting for the whole project, kept separate from your character sheet.
- Hex values written down, checked against the output rather than judged by eye.
- Positive style language in the locked block. Name the look you want, not the twelve looks you don't.
And separate your blocks. Keep the character description and the scene action as two distinct pieces of text, with a visible delimiter between them. Fuse them into one 300-word prompt and the model blends the two, which is how a character ends up wearing the background's colour palette.
Order matters inside the prompt too, which is a longer subject than it looks. We covered how to structure an AI video prompt separately.
Why don't start and end frame methods work across multiple characters?
A start frame fixes one moment. A video is thousands of moments.
Lock the opening and closing frames and the model interpolates everything between them. That interpolation is where a character turns, changes pose, or shows the back of their head, and those are the exact moments identity slips.
Now put two characters in frame. Every drift risk you had just doubled, and the model has to resolve both while also handling whatever movement you asked for.
Here is where the advice gets contradictory, and it is worth naming.
Google's AI Mode recommends chaining: feed the last frame of one clip in as the start frame of the next, to carry lighting and wardrobe forward. Google's AI Overview, on the same topic, warns against "copying copies" because errors compound when you generate from a generation rather than the original.
Both are right, at different lengths. Chaining across two or three clips preserves continuity. Chaining across thirty compounds every small error into a different person.
The working rule: chain from your master reference, not from the previous output. Re-anchor every five or six clips. Accept that each re-anchor costs you a generation.
More on the continuity errors that creep in around wardrobe, props and setting, which are the ones readers feel without being able to name.
Why does the visual style drift separately from the character?
Because they are two different problems and most advice only solves the first.
You can hold a face perfectly and still end up with scene three in soft pastel and scene twelve in hard contrast. Palette, line weight, lighting logic and rendering style all drift on their own schedule.
This is the complaint behind every "why do the visual styles in my music video scenes keep changing" search, and it rarely gets a real answer.
Treat style as its own locked asset. One style frame, written prohibitions, hex values, and the same style language in every prompt. Then check it separately from the character, because a shot can pass an identity check and still be visually wrong.
Style consistency is its own discipline, and worth reading up on separately if your palette keeps sliding.
How do you fix one shot without regenerating the whole video?
This is the question nobody answers.
Go looking and you will find guide after guide on preventing drift. Character sheets, prompt blocks, reference locking. All prevention, all written for someone who has not started yet.
Almost nothing is written for the person who already has a finished video with one bad shot in the middle of it.
On most clip-based tools, the answer is genuinely bad: regenerate the shot. Which is a fresh roll of the dice on your character, in a video where every other shot already matches.
A few tools do better. Luma and Higgsfield both offer video-to-video refinement, which preserves more of the original than a clean regeneration does. It is still a generation you pay for, on a clip you then re-stitch into the timeline yourself.
On LongStories, a bad shot is a shot, not a video. Open the video in the editor and fix that one image: edit it against the character reference, regenerate just that shot, replace the image, or restore an earlier take. Re-animate, re-render, done. The other forty shots never move.
Worth saying plainly: a saved character guides every generation without guaranteeing every shot matches. LongStories' own guide says exactly that, and tells you to review before publishing. The difference is not that nothing ever goes wrong. It is that when something does, you repair it instead of rerunning the project.
What this costs once you have twenty scenes
Every fix above is real. Every fix above is also something you perform again, by hand, for every generation, forever.
So how bad does that get?
Count it honestly for a ten-minute video on a clip-based tool:
Per video | |
|---|---|
Generations at 8 to 15 seconds per clip | 40 to 75 |
With a 30% retry rate | ~100 |
Identity checks you perform | one per shot |
Reference re-attachments | one per generation |
Then do it again next week for episode two.
This is the part the research backs up and the marketing does not mention. A 2026 benchmark from ByteDance and Rice University tested 140 multi-shot episodes across 2,491 shots and found cross-shot consistency degrades sharply with recurrence distance. The further apart two appearances of a character sit, the worse the match. Not a prompting failure. A property of the architecture.
Think of it like a film set where the continuity supervisor goes home after every shot and a new one arrives who has never seen the script. You can hand each of them a folder of photographs. You will be handing over that folder all day.
So the real question is not which prompt holds a character. It is whether the character is stored anywhere at all.
That is what a Universe does on LongStories. The cast, the places, the art direction and the visual style live in a saved world, and every video made inside it starts from that foundation. Nothing to re-attach. One generation runs up to fifteen minutes, so inside an episode there are no joins for drift to happen at.
Two things worth knowing before you plan a season. Editing a universe applies to new videos only, so your published episodes keep the version they were built with. And voices sit on the saved character rather than the universe, with each video choosing its own narrator.
Frequently asked questions
Why does my AI character look different in every scene?
Your model rebuilds the character from scratch on every generation, filling any detail your reference did not show with a plausible guess. Fix the reference first: front, three-quarter, side, back and close-up, plain background, nothing in the hands. Then lock a text block describing the character and paste it into every prompt unchanged.
How many reference images do I actually need?
Three to five. Most tools cap reference inputs at four anyway, and extra images get averaged into something softer rather than something more accurate.
Does a character sheet work better generated all at once?
Yes. Panels generated together share one interpretation of the character. Generated separately, each panel is its own guess, and you end up with a reference sheet that contradicts itself.
Can I fix a continuity error without regenerating the whole video?
On most clip-based tools, no, you regenerate the shot and accept a new roll of the dice. Luma and Higgsfield offer video-to-video refinement that preserves more of the original. LongStories edits a single shot inside a finished video and leaves the rest untouched.
Why do my videos look inconsistent when I produce at scale?
Because at scale you are not maintaining one character, you are maintaining one description across dozens of independent interpretations of it. The workflow that holds for five videos becomes a job at fifty.
Is there any tool that guarantees perfect character consistency?
No. Benchmarks built to measure it still find identity degrading the further apart two appearances sit. What changes between tools is how many opportunities drift gets, and whether anything remembers your character between videos.
Where to start
Making one video? Rebuild your reference sheet. Five angles, plain background, empty hands, wardrobe visible. Most drift people blame on prompting is a gap in the reference, and this fixes more of it than any prompt rewrite will.
Making a series? Then the reference sheet is the wrong layer to solve it at.
On LongStories your cast lives in a Universe instead of a folder, so every video starts from it. Fifteen minutes generate in one pass, so inside an episode there are no joins for drift to happen at. And when one shot does come back wrong, you fix that shot rather than the video.
Your continuity supervisor goes home after every shot. Either you hand over the folder each time, or you use something that keeps the folder.
LongStories is constantly evolving as it finds its product-market fit. Features, pricing, and offerings are continuously being refined and updated. The information in this blog post reflects our understanding at the time of writing. Please always check LongStories.ai for the latest information about our products, features, and pricing, or contact us directly for the most current details.